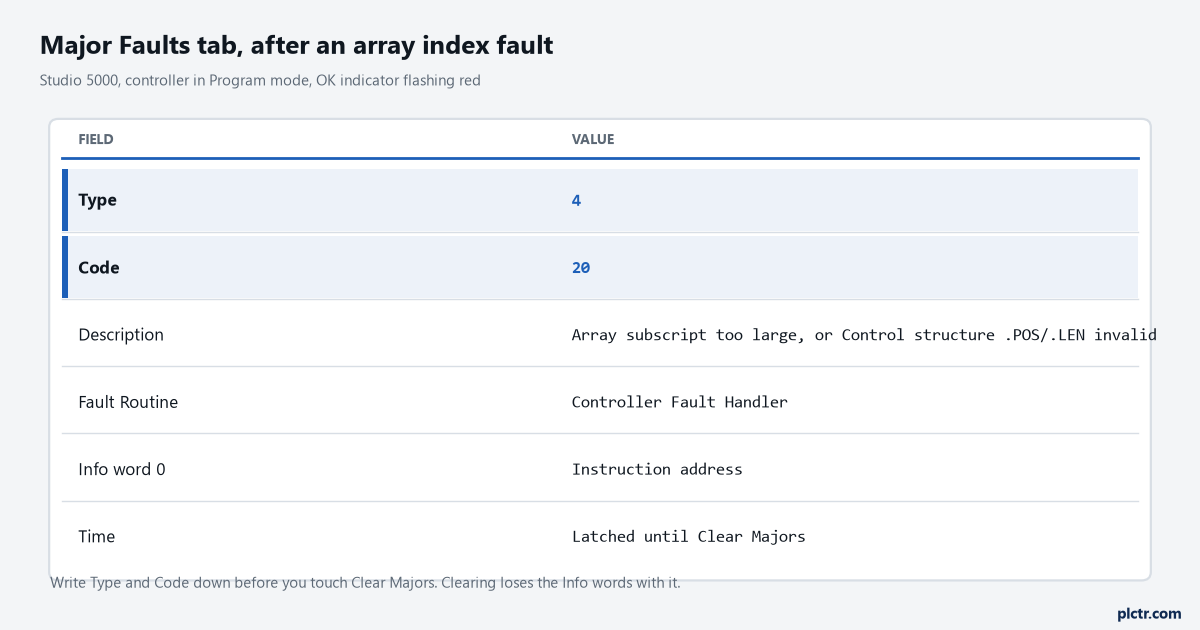
The controller is in Program mode, the OK indicator is flashing red, and the Major Faults tab in Studio 5000 reads Type 4, Code 20. Two numbers, and they are the whole diagnosis. An instruction reached for an array element that does not exist. Nothing is wrong with the hardware.
Type tells you which part of the controller gave up. Code tells you what it did. Write both down before you touch anything, along with whatever is in the Info words, because the reflex is to hit Clear Majors and go back to Run, and then the evidence is a memory.
One thing to get out of the way, because otherwise it costs an hour. The fault code tables are not printed in the manuals any more. Publication 1756-PM014O-EN-P, September 2024, has a section headed “Major fault codes” that runs half a page and finishes with “Refer to the Logix 5000 Controller Fault Codes spreadsheet for a complete list of fault codes.” The instruction reference, 1756-RM018A-EN-P, September 2025, says the same thing in three places. That spreadsheet sits in the Rockwell knowledgebase behind a free web account. No support contract needed, but you do need to be online, which is not always true at 2am in a switch room. What is still printed, and what most of this article is built from, are the per-instruction fault tables scattered through RM018A.
What the type number is routing you towards
The type is not a severity. It is a statement about where the fault came from, and it decides which fault routine gets the chance to handle it.
| Type | Condition | Where the handler belongs |
|---|---|---|
| 1 | The controller powered up in Run or Remote Run mode | Power-Up Handler |
| 3 | Communication with an I/O module failed | Controller Fault Handler |
| 4 | The execution of an instruction faulted | The program’s own fault routine |
| 6 | The watchdog timer for a task expired | Controller Fault Handler |
| 11 | A motion axis faulted | Controller Fault Handler |
Type 4 is the one you will meet most, and it is nearly always something you wrote yourself.
The type 4 codes worth knowing by heart
These come from the individual instruction pages in 1756-RM018A-EN-P, where Rockwell still documents the fault each instruction can throw. Page numbers are that manual’s own.
| Code | What the manual says causes it | Where to look first |
|---|---|---|
| 20 | A subscript exceeds its dimension. Any instruction that views an array as a collection of elements can raise it (p.883). Also SQL when position is greater than the size of Array (p.663), BSL when LEN exceeds the array (p.624), BSR when the first bit plus the bits to shift passes the end of the array (p.628), FFL when starting element plus .POS is past the end of the FIFO (p.633), FFU when the specified Length is past the end (p.639), LFL and LFU the same for a LIFO, DDT and FBC when result.POS exceeds the result array (p.716, p.724). PM014O adds that an invalid .POS or .LEN in a CONTROL structure lands here too. | The index tag, not the array. Something wrote a value the array cannot hold, and it is usually a counter that was never bounded. |
| 31 | A JSR has fewer input parameters than its SBR, a RET has fewer return parameters than the JSR that called it, or the main routine contains a RET (p.680). | The two parameter lists, side by side. This one shows up after somebody adds a parameter at one end only. |
| 34 | A timer’s .PRE or .ACC went negative (p.112, p.123 and p.133 for RTO, TON and TOF). | Whatever writes the preset. A scaled recipe value or an operator entry with no limit check will do it. |
| 51 | The LEN value of a string tag is greater than the DATA size of that string tag (p.838). | Anything writing to the .LEN member directly. Rockwell’s own recovery note is to check that no instruction is writing to LEN. |
| 52 | The output string is larger than the destination (p.838). | The destination string type. Make a bigger one rather than truncating upstream. |
| 56 | The Start or Quantity value is invalid (p.838). Start has to sit between 1 and the DATA size of the Source. | String instructions that count from 1, not 0. That catches people who came from C. |
| 82 | A FOR instruction called a subroutine that is an SFC and is already executing, so a recursive call (p.707). | The call tree. |
| 85 | SFP or SFR was pointed at a routine that is not an SFC routine (p.691, p.693). | The routine name operand. |
| 89 | SFR names a target step that does not exist in the SFC routine (p.693). | A step that got renamed. |
| 94 | The FOR nesting level limit of 25 was passed (p.707). | Recursion you did not intend. |
| 990 to 999 | Reserved for user-defined faults. A JSR that jumps to a fault routine also reports 990 or a user-supplied code (p.680, and PM014O p.21). | Your own code. Somebody deliberately shut the controller down. |
Code 20 is far and away the one you will meet, and the trap in it is that the array looks innocent when you go online and stare at it. The subscript has already moved on by then. Put the index on a trend, or latch a copy of it in the fault routine, or you will spend the shift watching a number that is fine.
Type 6 code 1 means your logic ran, and ran, and ran
The task watchdog expired. Nothing threw an error. A construct simply did not finish, and RM018A names the three that do it: FOR…DO, REPEAT…UNTIL and WHILE…DO, each documented with fault type 6, fault code 1, “the construct loops too long.”
A REPEAT_UNTIL always runs its statements at least once and checks afterwards. A WHILE_DO checks first and might never run at all. Get those two the wrong way round with an index that steps by 2 and a terminal value that is odd, and the exit condition is never true, because the index skips straight over it. The controller has no way of knowing that. It runs the loop until that task’s watchdog gives up on it, and then the whole controller goes to Program mode over one bad terminal value in one line of Structured Text.
So check the exit condition first, before you go anywhere near the task properties.
Type 1 code 1 is the controller asking permission
Power came back and the keyswitch was in Run. The controller will not just start driving outputs. It raises type 1 code 1 and sits in the faulted state, and that is deliberate.
Leave the Power-Up Handler empty and it stays there. That is the safe default and the right answer on a machine where a restart has to be a decision somebody makes. If the process genuinely has to come back on its own, PM014O is specific about the order: clear the type 1 code 1 fault in the Power-Up Handler routine first, then run the logic that does the specific actions. Clear, then act.
Minor faults do not stop the controller, which is the problem
Nothing flashes. The machine keeps running. The controller logs the fault, carries on, and six months later somebody works out that the battery died in March and the project everyone has been editing online is the only copy that still has this year’s recipe data in it.
Put a GSV on the FaultLog object’s MinorFaultBits attribute into a slow task and watch four bits:
- Bit 6, task overlap. A periodic task was still running when its next interval came round.
- Bit 7, load from nonvolatile memory.
- Bit 9, serial port fault.
- Bit 10, low battery, or depending on the controller the energy storage module or the UPS is missing or wants replacing.
Two catches. Math overflow minor faults are not reported at all unless Report Overflow Faults is ticked on the Advanced tab of Controller Properties, so a quiet minor fault log is not proof of a clean one. And S:MINOR stays set until the end of scan, so if you are testing whether one particular MUL overflowed you have to clear S:MINOR on the rung before it, run the instruction, then check. Otherwise you are reading somebody else’s fault.
PM014O’s own example puts that GSV behind a one minute self-restarting timer, 60000 ms, on the grounds that reading the fault log every scan costs scan time for nothing. Reasonable trade on a busy controller.
Reading the fault from logic instead of from the screen
The Major Faults tab is fine when you are standing at the laptop. It is no use at all when the fault happened at 3am on Sunday.
Build the user-defined type Rockwell documents and get it in front of an HMI. Members: Time_Low as a DINT, Time_High as a DINT, Type as an INT, Code as an INT, Info as DINT[8]. Then GSV the Program object’s MajorFaultRecord attribute, which is a DINT[11], into a tag of that type, passing THIS as the instance name when you want the program that contains the instruction.
Clearing it from logic is the same trip in reverse. Write zero into the Type and Code members, then SSV the whole record back. Because Type and Code are zero, the fault clears and the controller runs again.
Clearing faults from logic is a decision, not a habit
This is where a fault handler stops being a convenience and turns into a liability, and PM014O is blunter about it than most Rockwell documents get. Do not use fault routines to continually clear all faults on the controller. Be selective about which types you clear and how many.
The mechanism behind that warning is worth understanding, because it is not obvious from the outside. When an instruction faults, that instruction is skipped and does not run. If the faulted instruction happened to be a JSR, the whole subroutine behind it is skipped, and everything inside that, and a handler that quietly clears a code 20 on every scan will therefore keep the controller in Run while a section of the program has stopped executing, with nothing on any screen anywhere to say so.
The machine runs. Part of it is not being controlled.
Add-On Instructions behave the same way and are worse to debug. A fault inside an AOI aborts the remainder of that AOI, and if the fault clears, execution resumes at the instruction after the top-level AOI call. Nest three deep and a fault in the innermost one abandons all three, while the rung after the outermost carries on as though nothing happened.
There is one place where automatic clearing already happens and is fine. From controller revision 13.0 onwards, an array subscript out of range during prescan is cleared by Logix Designer’s own internal handler, which touches only array faults of type 4, codes 20 and 83, and only during prescan. It does not do it during postscan, because the user program owns the index values when an SFC action shuts down. On revision 11.x and earlier that same prescan condition produced a real major fault, which is why an old project sometimes faults the instant you go to Run and never before.
I/O and message faults use a different set of numbers
A type 3 fault is a module connection that failed, and what you get back is a CIP number rather than a fault code. Depending on where it surfaces you see the full hex, 16#000A, or only the tail, #000A. Look on the Connection tab of the module’s Properties dialog, and for the yellow warning triangle in the I/O Configuration tree.
MSG instruction errors have their own table in RM018A. The useful part is the extended codes that sit under error 0001, connection failure:
| Extended code | Meaning |
|---|---|
| 0106 | Ownership conflict |
| 0107 | Connection not found |
| 0109 | Invalid connection size |
| 0110 | Module not configured |
| 0114 | Wrong module |
| 0115 | Wrong device type |
| 0116 | Wrong revision |
| 011A | Application out of connections |
| 0203 | Connection timeout |
| 0204 | Unconnected message timeout |
| 0311 | Port not available |
| 0315 | Invalid segment type |
The pair worth separating is 0203 and 0204. A connection timeout means a connection existed and stopped answering, so go and look at the device or the path to it. An unconnected message timeout means the request never got a connection at all, which points at the route in the MSG configuration rather than at the far end.
Under error code 00FF, general error, sit the ones that are not really faults: 2101 invalid keyswitch position, 2108 controller in upload or download mode, 2113 controller in faulted mode, 2114 run mode inhibited. If a MSG that worked yesterday is failing today, check those four before you check the network.
Frequently asked
Where has the fault code list gone?
Into a spreadsheet in the Rockwell knowledgebase. Both 1756-PM014O-EN-P and 1756-RM018A-EN-P now point at it instead of tabulating the codes. A free Rockwell web account gets you in. Keep a copy locally.
Is type 4 code 20 ever a hardware problem?
No. It is an index that went out of range. The array is the victim.
Why did the controller fault the moment I went to Run, when it was fine in Program?
Prescan. On revision 11.x and earlier an out-of-range subscript during prescan produced a major fault. From revision 13.0 the application clears array faults of type 4, codes 20 and 83, during prescan only.
How do I make my own fault?
Set fault type 4 and pick a code between 990 and 999, which Logix Designer reserves for user-defined faults. The controller then treats it like any other major fault, goes to Program mode and drives outputs to their configured faulted state.
Can I test a fault routine without breaking something?
Yes. Point a JSR at the program’s own fault routine from a conditioned rung. Rockwell documents that as the way to simulate a fault, and it reports as type 4 with code 990 or the code you supplied.
Next step
Get the fault record off the controller and somewhere a person will see it. A GSV into a FAULTRECORD tag, four HMI fields and a timestamp is an hour of work, and it pays for itself the first time somebody rings about a stoppage that happened two shifts ago. The mechanics of building the handler are in the PLC controller fault routine and creating a controller fault routine, and the deliberate version is in creating a user-defined fault. For the code lists themselves, see ControlLogix major fault codes and ControlLogix minor fault codes. For connection problems specifically, Allen-Bradley I/O faults.
Primary sources: Rockwell Automation, Logix 5000 Controllers Major, Minor, and I/O Faults, publication 1756-PM014O-EN-P, September 2024; Rockwell Automation, Logix 5000 Controllers General Instructions, publication 1756-RM018A-EN-P, September 2025.